Paying Rent on a Log File
The token tax nobody budgets for, and what I built to fix it
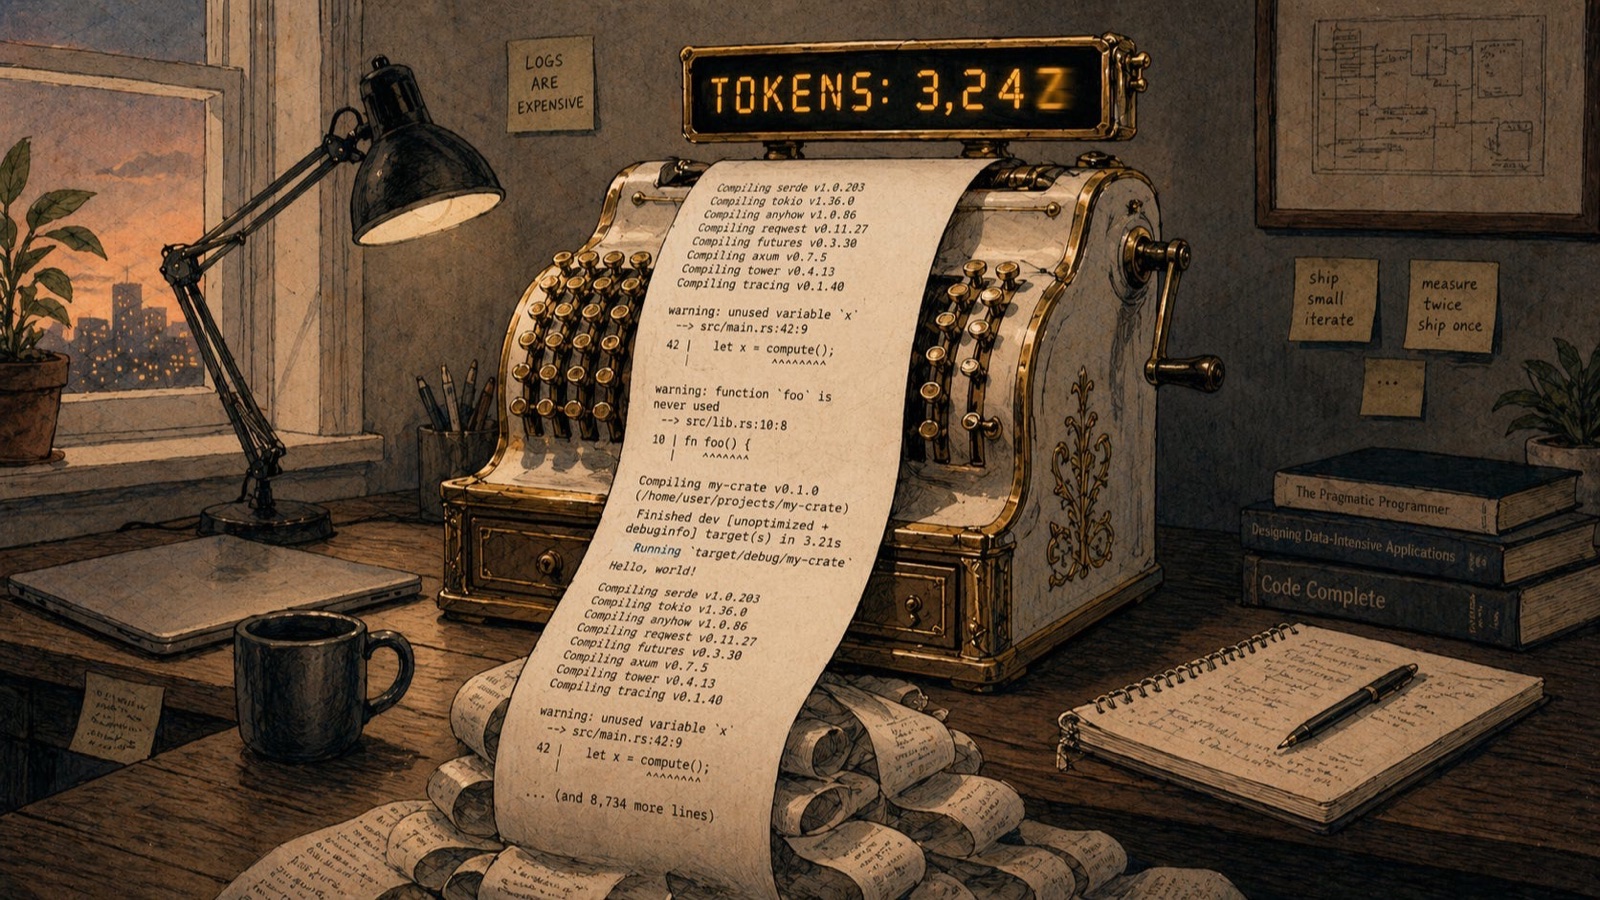
Priya runs the platform team at a mid-sized SaaS company. Thirty engineers use Claude Code daily. A few months in, Finance pings her: the AI coding bill has tripled. Headcount didn’t change. Feature velocity is about the same. What gives?
She digs. Model pricing hasn’t moved. Prompt sprawl is under control. No agent is stuck in a loop. The culprit turns out to be the shell output.
Every time an engineer’s agent runs cargo build or npm install or kubectl describe pod or terraform plan, the tool emits hundreds or thousands of tokens of log output. The agent reads all of it, decides whether anything matters, and moves on. Ninety-plus percent of that text is noise the agent ignored. It still got billed.
At thirty engineers running a dozen shell calls an hour, the numbers are what they are. Call it a few dollars per engineer per day in pure log-scraping. Per year, that’s real money. And it’s invisible in every tool Priya already has, because token costs don’t break down by what the tokens were for.
Welcome to the token tax.
The shape of the problem
Here’s what makes this one insidious. The model doesn’t know the output is noise until after it reads it. The engineer doesn’t see the output at all; the agent summarizes in one line and moves on. Finance sees an aggregate bill. Nobody in the loop has any visibility into the fact that cargo build --release just burned 3,200 tokens of “Compiling serde v1.0.203…” to produce a one-word conclusion.
Verbose compilers, chatty cloud CLIs, and test runners that print a line per passing case are the three biggest offenders in most shops. Every dev tool writes more to console than it needs to, because historically a human was reading it. A human skims a cargo build log in half a second. An agent pays for every byte.
Multiply that across a team, then across a company’s deployed fleet of agents, and the cost stops being a rounding error. For the companies running Claude on-prem or on cloud VMs at serious scale, the token-tax line item can eclipse whole categories of traditional infrastructure.
Why the obvious answers don’t land
I spent a while poking at this before I started writing code. A few things other people have tried, and why none of them satisfied me.
Truncate the output. Some shells let you cap tool output at N kilobytes. This works until the important bit is in the last kilobyte. Compilers put errors at the end. Cloud CLIs often bury the actual failure under status banners. Blind truncation drops the signal and keeps the noise.
Have the agent summarize first. Pipe the output through a small model that summarizes, then hand the summary to the main agent. This adds latency, costs its own tokens, and worst of all, it rewrites the content. Now your main agent is making decisions based on a hallucinated summary of its own build log. If the summary drops a warning that mattered, you’d never know.
Per-tool hand-tuned filters. Write grep patterns for each dev tool. This works for the five tools you bothered to write filters for, and it rots the first time a tool’s output format changes. Nobody wants to maintain that.
Move to a smaller model for shell parsing. Same failure mode as agent summarization. You pay for the compression step, and you introduce a reasoning gap between what the tool actually said and what the agent thinks it said.
The pattern I wanted was different. A layer that sits right at the shell boundary, drops lines that don’t matter, keeps the ones that do, and never rewrites anything. If the cargo build log says “warning: unused variable x“, the agent should see exactly that string. If it says “Compiling serde v1.0.203”, the agent should see nothing at all, because that line would not have changed what the agent does next.
So I built one.
NID
NID is a Rust CLI I’ve been working on. It lives at github.com/newtro/nid, which is my GitHub handle. Apache-2.0 or MIT license, pick your poison. If you’ve seen my byline around JnyCode or 42 Insights, this is the thing I’ve been building in the background for the last few months.
What it does is simple. It sits between your AI coding agent and the shell. Output goes in one side. A compressed version comes out the other. The agent’s prompt, tools, and model stay exactly the same. The shell just got quieter.
I haven’t run a formal benchmark against a specific workload yet. The numbers I see in practice land in the 60 to 90 percent token reduction range on typical dev tool output when I toggle the hook on and off during real agent sessions. Your mileage will depend on which tools your team runs and how chatty they are.
A few design choices worth flagging, because they took the longest to get right.
Profiles are bundled, and the tool learns new ones. NID ships with twenty pre-built profiles for the usual offenders: git, cargo, pytest, npm, docker, kubectl, terraform, aws, and so on. Each profile is a TOML file that declares what to keep and what to discard for that tool’s output. If you run a command NID doesn’t have a profile for, it watches the output. After five samples, or three byte-identical runs, it synthesizes a profile automatically. The thresholds are deliberately conservative. On a novel tool, undercompression just wastes a few tokens. Incorrect compression creates silent bugs that are very hard to find later.
Fingerprinting is canonical. I wrote a scheme called Scheme R that normalizes flags, argument order, and environment so that cargo build --release and CARGO_TERM_COLOR=never cargo build --release map to the same profile. Without canonicalization, every minor variation forks a new learning bucket and the self-synthesis feature never converges. This was the single hardest design decision in the project. Getting it close to right took weeks.
Four tiers of fidelity checks. T1 through T4, increasing in strictness. At T1, NID just verifies it’s not dropping lines that match any error-like pattern. At T4, it reruns the same command twice and confirms that the compressed output would lead a parser to the same semantic conclusion. I default most profiles to T2 or T3. You can bump a profile to T4 for anything your agent is parsing downstream, like kubectl get pods -o yaml.
PreTool hooks for eight agents. NID ships installers for Claude Code, Cursor, Codex, Gemini, Copilot, Windsurf, OpenCode, and Aider. For Claude Code, it’s one line in .claude/settings.json, and the installer writes it for you. Readers of my “One Prompt to Rule Them All” and “One Commit to Update Them All” posts already know where that file lives and how to ship changes to every agent in the company. Drop NID into your config repo, push, and the next refresh pass rolls it out to the fleet.
The invisible-to-line-itemed move
The reason I think this matters, and the reason I spent the time to ship it rather than just complain about the cost, is that a tool like NID turns the token tax from invisible to measurable. You can toggle the hook on and off for a week and read the difference straight out of your billing dashboard. That’s the kind of number a VP of Engineering can put on a slide. It’s also the kind of number that makes “deploy Claude agents to 500 engineers” go from a scary finance conversation to a boring finance conversation.
I’m not going to pretend NID is a finished tool. Three stars and fifteen commits as of this morning. The profile library is smaller than I want it to be. The docs need another pass. There are edge cases in Scheme R I’m still finding. If you deploy it tomorrow, you’re deploying a solo-author Rust project with a strong design and a young codebase. Great fit for a canary ring. Not yet where I’d put it in front of a regulated-industry stable fleet without running it through your own fidelity tests.
The design is the part I’m confident about. The problem is real. The shape of the answer is right. And the integration channel (PreTool hooks plus the config-repo pattern) is already built into the way serious teams are deploying AI today.
If the token tax is showing up on your bill, or you suspect it will once your fleet scales, I’d love you to try it. Repo is at github.com/newtro/nid. Issues, pull requests, and new profiles all welcome. If you’re a regulated shop and you want to talk about enterprise deployment, you know where to find me.
The log file isn’t going to stop being noisy. Your agent shouldn’t have to pay for it. Github repo: https://github.com/newtro/nid
Scott writes 42 Insights on the patterns showing up in enterprise AI adoption. He runs an AI consulting practice at johnnycode.ai and builds open-source tools under the “newtro” handle on GitHub. NID is the first of them he’s written about here.
First published April 22, 2026 on 42 Insights.
Get new posts by email
One email when something new goes up. Nothing else, ever.
You will get a confirmation email first, and every post has an unsubscribe link. Prefer a reader? Use the RSS feed.