Every AI IDE Is Doing Context Management Wrong
And I think I know how to fix it.
I’ve been building with AI coding tools for a while now. Cursor, Copilot, Claude Code, Windsurf. They all have the same fundamental problem, and none of them are solving it.
They’re dumb about context.
The Problem Nobody Talks About
Here’s what happens in every AI coding session right now. You start a task. The AI reads some files. Makes some edits. Runs some commands. Gets errors. Reads more files. Tries again.
Twenty minutes in, your context window is stuffed with raw terminal output, full file contents you looked at once, compiler warnings from three attempts ago, and the complete text of every exchange you’ve had. Most of it is irrelevant to what you’re doing right now.
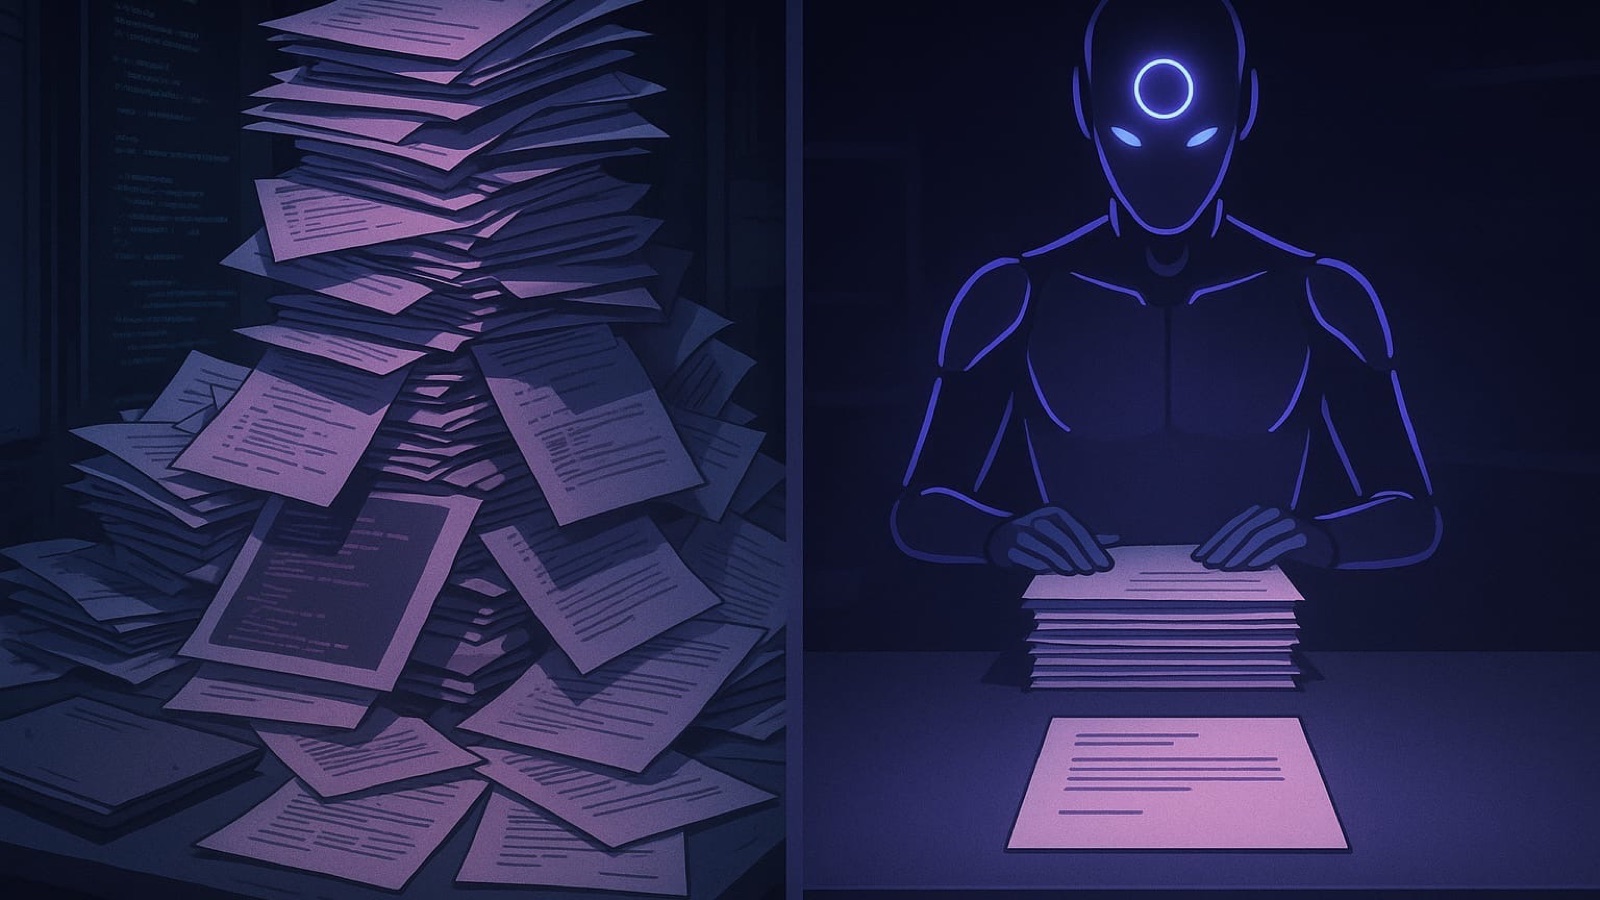
The AI is essentially trying to work at a desk piled six feet high with every document it has ever touched. And you’re paying for every single token of that pile, every single turn.
Current solutions fall into two camps. Either the tool sends everything to the model every time (expensive, slow, and eventually hits the context limit), or it naively truncates old stuff (and inevitably throws away the one thing it needed to remember).
Neither approach is good enough.
What If the AI Had an Executive Assistant?
I’ve been working on an IDE called Archon, and the core idea came from a simple question: what if a smaller, cheaper model managed context for the bigger, more capable model?
Think about it. Anthropic’s Sonnet 4.5 has a million token context window. It can hold an entire coding session in memory. Every file, every command, every conversation turn, every error. All of it. Nothing gets thrown away.
But you don’t need the expensive model to remember all that. You need the expensive model to think hard about the problem in front of it right now.
So the architecture looks like this:
- You send a prompt
- Sonnet (the smaller model) looks at your prompt, looks at the entire session history it’s been holding, and decides what’s relevant
- Sonnet builds a focused briefing. Maybe 20k tokens of exactly what the big model needs to see
- Opus (the big model) receives that clean briefing and does the hard thinking
- Repeat
Opus shows up to every turn with a clean desk and exactly the right files on it. Sonnet is the executive assistant who prepared everything.
But it gets better. Not every turn needs Opus at all. Sonnet can handle simple follow-ups, confirmations, and straightforward code generation on its own. So you end up with three tiers:
- Sonnet handles it directly (cheap, fast)
- Sonnet curates context, Opus executes (right-sized cost)
- Full context to Opus (rare, only when needed)
The token savings are significant. On a long session, you might cut costs by 60-70% while actually getting better results, because Opus isn’t distracted by irrelevant noise.
But That’s Only Half the Idea
The second piece is maybe more interesting. What if you could design your own AI workflow?
Right now, every AI IDE gives you a fixed agent loop. You can’t change how it thinks. You can’t add a review step. You can’t route different types of tasks to different models. It’s a black box.
Archon has a visual flow editor. Drag and drop nodes to design your own agentic loop:
- LLM nodes where you pick which model handles what
- Tool nodes for file operations, terminal, search
- Router nodes that branch based on task complexity or type
- Memory nodes for reading and writing state
- Human checkpoints where you want approval before the AI continues
Want a dedicated code reviewer that checks every edit before it gets committed? Wire one up. Want to run two models in parallel exploring different approaches and pick the better result? Build that flow. Want the AI to automatically pull test results and error logs before it even starts thinking about a bug? Design it.
The key insight is that there’s no single best way for an AI to approach coding tasks. Different codebases, different languages, different developers all want different things. So stop prescribing one loop and let people build their own.
The Debuggability Problem
There’s a side benefit that I think matters just as much as the performance gains.
When you can see the flow, you can see what’s happening. You can watch a request move through your pipeline in real time. You can see what the curator model selected as relevant context. You can see what the executor model actually received. You can see where your tokens went.
Try doing that in Cursor or Copilot. You can’t. It’s a black box. You type, something happens, you hope it’s good.
Developers don’t like black boxes. We debug everything else. We should be able to debug our AI tools too.
Does Anything Like This Exist?
I looked. The short answer is no. Not as a complete package.
IBM announced Project Bob last year. It orchestrates multiple LLMs and picks the right model per task. But it’s enterprise-focused, closed source, and you have zero control over the orchestration logic.
Cursor uses what they call an “Embed-Think-Do” loop with different models for different operations internally. Smart approach, but completely hidden from the user.
Tools like Langflow and Dify let you build visual AI workflows, but they’re generic platforms. None of them are integrated into a coding environment.
MemGPT (now Letta) pioneered tiered memory management for agents. Similar philosophy to what I’m doing, but it uses the same model for everything and isn’t built for coding.
The gap is clear: nobody is combining tiered multi-model context management with a visual flow designer inside a purpose-built coding IDE.
Where This Goes
Once developers can share their flows, something interesting happens. A “React Refactoring Flow” optimized by someone who’s done hundreds of refactors becomes available to everyone. A “Rust Memory Safety Review” with a dedicated model checking for unsafe patterns gets published and improved by the community. Flows become a new kind of open source artifact. Not code, but AI thinking patterns.
That’s the part I’m most excited about. The marketplace of ideas, literally.
Building in the Open
I’m going to document the build process here. The architecture decisions, the tradeoffs, what works and what doesn’t. If you’re interested in how AI tools actually work under the hood, or if you’re building something similar, stick around.
Next time I’ll dig into the technical architecture. Tauri, Rust, and why the context engine doesn’t always need an LLM.
If you have thoughts, I want to hear them. Reply, comment, tell me I’m wrong. This is an idea that gets better with feedback.
Scott Smith has been writing code for 41 years and still gets excited enough about new ideas to stay up until 5 AM.
First published February 11, 2026 on 42 Insights.
Get new posts by email
One email when something new goes up. Nothing else, ever.
You will get a confirmation email first, and every post has an unsubscribe link. Prefer a reader? Use the RSS feed.