AI Does the 80% That Looked Like the Job
A two-sided rubric for what to automate, what to protect, and why most AI deployments point at the wrong target.
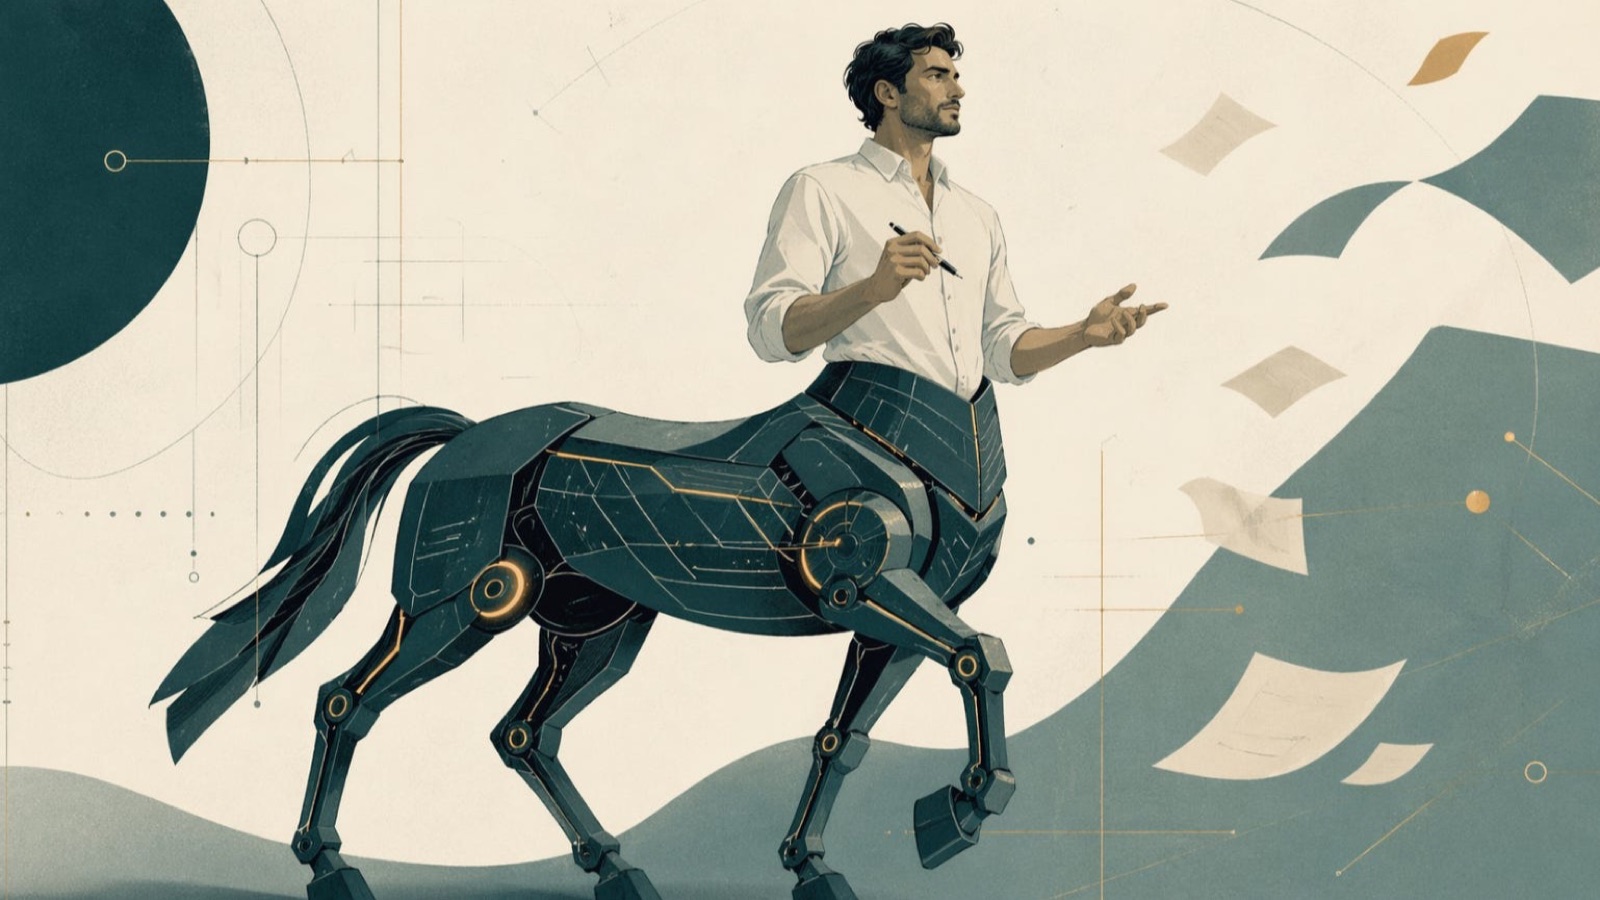
Every exec I talk to starts in the same place. They ask what AI can do. I’d rather hear them ask what AI should do first.
Before anyone can answer that honestly, though, we have to clear a piece of bad research out of the conversation.
Don’t Panic (Especially Not About the Failure Rate)
Your LinkedIn feed has been telling you that 95% of enterprise AI deployments fail. The number traces to an MIT NANDA study from July 2025 that went viral inside a weekend and has been repeated in every exec deck since. It deserves a harder look.
Wharton’s Kevin Werbach read the full report and found that the 95% figure appears in a single sentence with no supporting methodology behind it. The closest actual data point is a 5% success rate among “custom enterprise AI tools,” with success narrowly defined as marked and sustained productivity or P&L impact. A deployment that saves thirty hours a week but doesn’t move a P&L line counts as failure by that definition. Werbach’s public position was that the report should either release its full data or be retracted.
The study also came from the NANDA project, a Media Lab spinoff building agentic protocol infrastructure on top of MCP and A2A, with authors who have product in the game. The connection to MIT proper is loose. Futuriom called the whole thing “propagandized clickbait” after trying to reconstruct the methodology from charts with unlabeled axes. Their independent database of 130+ documented enterprise AI deployments, with named companies like JPMorgan, Nestle, Novo Nordisk, and Mastercard posting measurable gains, is incompatible with a 95% universal failure rate.
The model vintage matters too. The study’s own methodology note confirms data was collected between January and June 2025, which means the deployments it measured were built on GPT-4 and Claude 3.5 era systems, with the tooling available at the time. A year later, the frontier models are meaningfully more capable, and the development stack around them, Claude Code among others, has compressed build time from months to weeks. A 2024-vintage failure rate applied to 2026 decisions is a category error.
Plenty of enterprise AI deployments genuinely underperform. The panic number that has been shaping Fortune 500 budget decisions, though, is a stretched inference from a small, undisclosed sample, amplified by a press cycle that loves a clean percentage.
A longer post dissecting the NANDA report and what it got wrong is in the works. For this piece, the short version is enough.
The real problem with enterprise AI is smaller and more fixable. Teams are pointing powerful tools at the wrong processes.
Two Ways to Waste Money
There are two ways to waste money on AI automation. You automate something you shouldn’t have, and you break a process that was holding the business together quietly. You skip automating something you should have, and you leave your expensive people doing cheap work.
Most execs worry about the first one. The second one costs more.
The fix is a scoring rubric you can run any process through in under five minutes. Half of it checks whether a process deserves automation. The other half checks whether it needs a human in the seat. You apply both, because some processes are good candidates to automate and still require human judgment on the final call. That’s called a centaur, and it’s where most of the real value lives.
Part One: Green Light Factors
A process is a good candidate for AI automation when it scores well on five questions.
1. Frequency. Does this happen ten or more times a week? Daily wins beat monthly wins by about 30x on ROI, and frequency is what lets the model and the humans around it develop a feedback loop. Automating something that runs once a quarter is a science project. Automating something that runs 400 times a day is a business.
2. Structured artifacts. Is there a clear input and a clear output? Email in, CRM entry out. Call recording in, SOAP note out. Invoice PDF in, approval routing out. If you can name the artifacts on both ends, you can automate the flow. If you can’t name them, you’ll end up automating a mess you haven’t understood yet.
3. Tolerable error profile. If AI gets it 85% right on first pass, does that save ten hours or break the business? Reversibility matters more than raw accuracy here. A draft email a human reviews before send tolerates 85%. A wire transfer does not.
4. Available ground truth. Do domain experts exist who can review output, correct it, and feed that correction back? Without a human-graded loop, quality decays. A lightweight review process works. One person who cares enough to flag bad output when they see it is often the whole pipeline.
5. Bottleneck cost. Is someone expensive stuck doing this? A VP reading 200 resumes a week is a better automation target than an intern filing them. Hit the expensive bottleneck first, because the hours you free up compound into strategy work that AI can’t do.
A process that scores four or five out of five is a green light. Two or three means build it with a human review step. Zero or one is a distraction.
Invoice matching, ticket triage, meeting notes, first-draft anything, research synthesis, document extraction, quality checks, classification, summarization. These categories tend to score well. The successful AI deployments I’ve seen all started in this territory, running something genuinely tedious and low-stakes until the team learned how to operate agents before trying to run important ones.
Part Two: What Requires a Human
Here is where most AI strategy decks go silent. The same rubric, inverted, tells you what to leave alone.
1. Accountability sinks. When this goes wrong, somebody has to own it legally, contractually, or reputationally. AI can draft the decision. A person signs it. Hiring decisions, firings, refunds above a threshold, pricing concessions, anything that could end up in a deposition. The EU AI Act Article 14 codifies this for high-risk systems in Europe, and the logic applies everywhere. The person who catches blame for a bad call needs the power to prevent it. If those two separate, you don’t have oversight. You have a liability transfer dressed up in ceremony.
2. Relationship-bearing work. The process itself is the relationship. A quarterly business review with your biggest customer. A 1:1 with a direct report. A board update. The efficiency gain here is a loss, because the point of the meeting is that you spent the time. An AI-summarized condolence note is an insult with good grammar.
3. Judgment without clear ground truth. AI is strong at the 80% middle of a normal distribution. It’s weak at “is this even the right thing to build.” Strategy calls, pivots, market entry, brand voice decisions, talent bets on specific people. You want a human setting the target, with AI hitting it.
4. Novel situations. LLMs interpolate well and extrapolate badly. The first time something happens at your company, a human should handle it. Then you codify what worked into something AI can run the next twenty times.
5. Acts where the doing is the point. A founder writing their own all-hands script. A leader showing up for a hard conversation. A handwritten note. Automating these hollows out the signal they were meant to send. The output exists to prove the input, and AI breaks that proof.
A “yes” on any one of these is a flag. Two or more means the human stays in the seat regardless of how good the model gets.
Part Three: The Layering Move
Here is the insight that changes how you build.
Most execs try to automate the decision and leave the gathering manual. They have it backwards. The right move is to automate the gathering, the drafting, the summarizing, the triaging, the first pass. Keep the decision, the relationship, and the accountability with a human.
The teams that succeed do process archaeology first. They watch people work, ask “what do you do when X happens” forty times, and build a ground-truth process map before touching a single agent config. Then they design for human-in-the-loop from the start, with AI handling the repetitive layer and humans handling the consequential one. The teams that fail skip this step and try to automate the PowerPoint version of a process, which is almost never what actually happens on the ground.
This is how you get a centaur instead of a reverse centaur. In a centaur, the human makes the decisions and AI handles the labor. In a reverse centaur, the AI makes the decisions and the human provides labor and legal cover by clicking approve on outputs they didn’t have time to actually review. The first one compounds value. The second one is a lawsuit waiting to happen.
The Babel Fish Test
In Hitchhiker’s Guide, the Babel fish is the perfect piece of automation. You put it in your ear and it silently translates every language in the galaxy. You don’t think about it. You don’t manage it. It does the part of communication that was friction, leaving you with the part that was actually the conversation.
That is the target. Automate the translation layer. The understanding stays yours.
The right move is to treat AI as a replacement for everything that used to stand between you and thinking. The thinking itself remains a human job.
AI does the 80% that looked like the job. Humans do the 20% that was the job.
Point it at the right 80%, and you stop being the failure statistic your consultants keep quoting.
First published April 24, 2026 on 42 Insights.
Get new posts by email
One email when something new goes up. Nothing else, ever.
You will get a confirmation email first, and every post has an unsubscribe link. Prefer a reader? Use the RSS feed.